Keep your technology
working, improving,
and delivering value.

Launching an AI solution is only Day One. In production, models drift, traffic surges, and token costs escalate. We provide 24/7 Managed AI and MLOps that keep enterprise environments reliable, secure, cost-governed, and continuously optimized.

99.9%*
Target Availability
-40%*
Inference Spend
< 15m*
Response Time
Zero*
Unmonitored Drift
* 99.9% target availability applies to managed gateways; client VPC deployments inherit host cloud (AWS/GCP/Azure) and upstream model SLAs. < 15m applies to emergency triage.
Managed AI Operations Cockpit
01
Distributed Tracing· Monitor API latency, model token queues & cluster health
Active
02
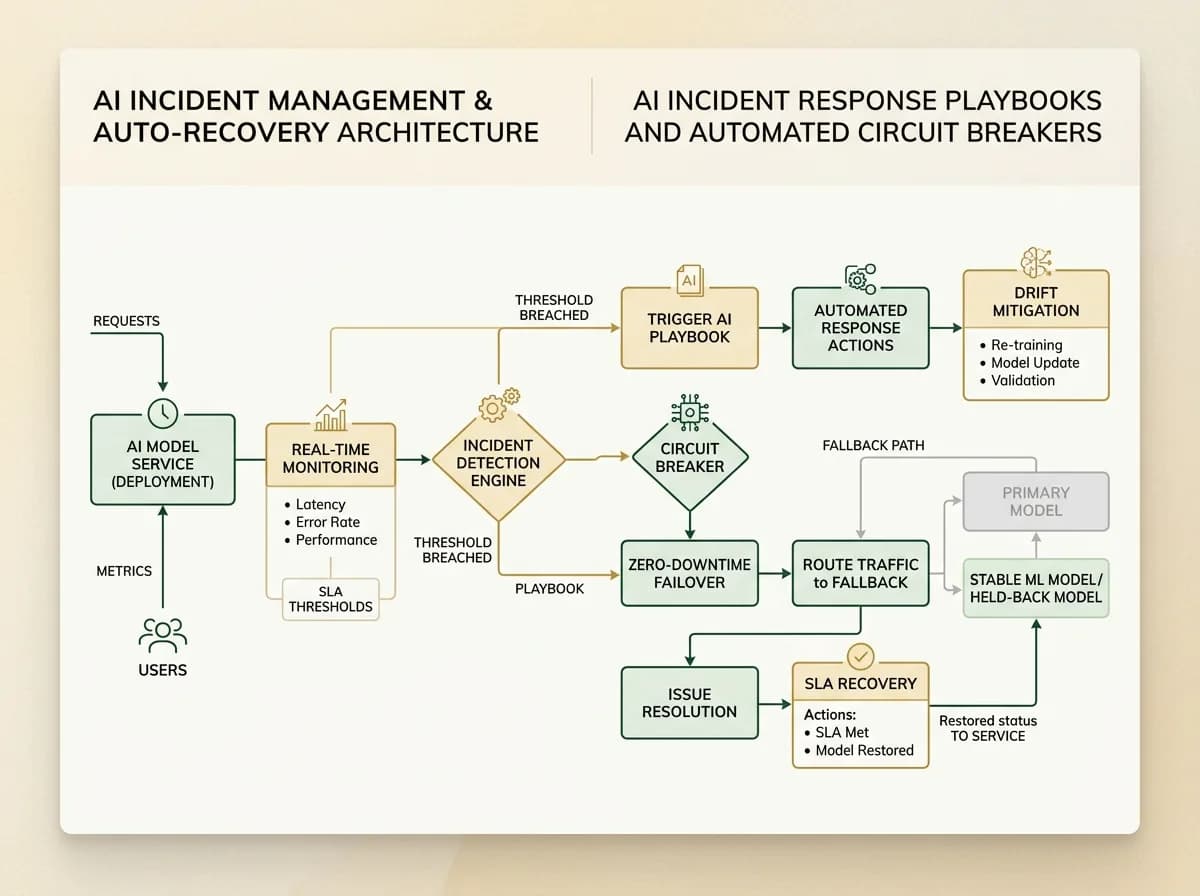
Breach Detection· Instant anomaly trigger within 60s of SLA deviation
03
Auto-Routing· Dynamic load diversion across multi-region Kubernetes nodes
04
SLA Assurance· Nominal latency restored with zero dropped user requests
Live:SYS: All 3 cluster nodes reporting healthy (latency P99: 118ms)
24/7 SRE
Projected SLA: 99.9%* Target · Multi-Zone
P99: 118ms · 3 Clusters Healthy
01 | Day-2 Operations & Ongoing Reliability

Launch is only the beginning. Management creates lasting value.

We manage the complete operational lifecycle, turning your production deployment into an engine of continuous improvement. Three core pillars keep your systems reliable, optimized, and compliant.
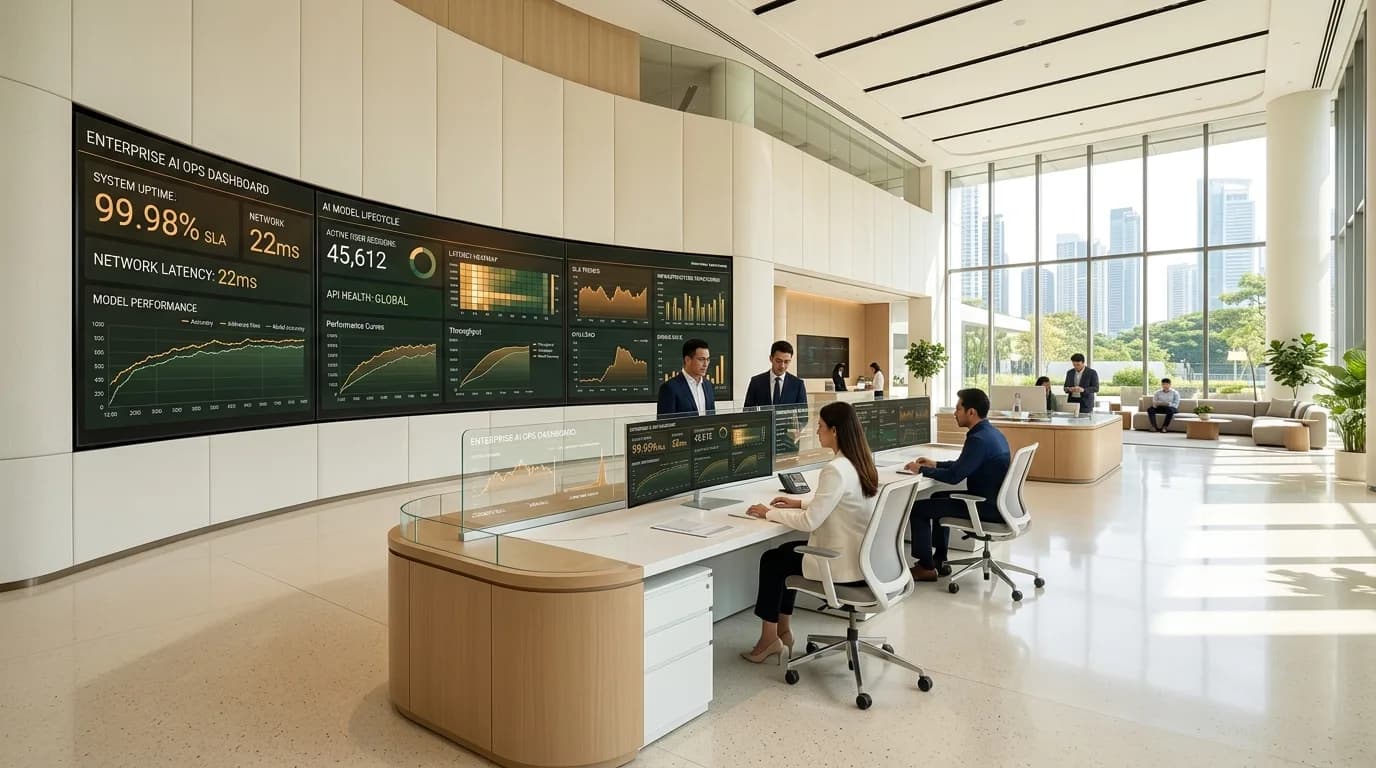
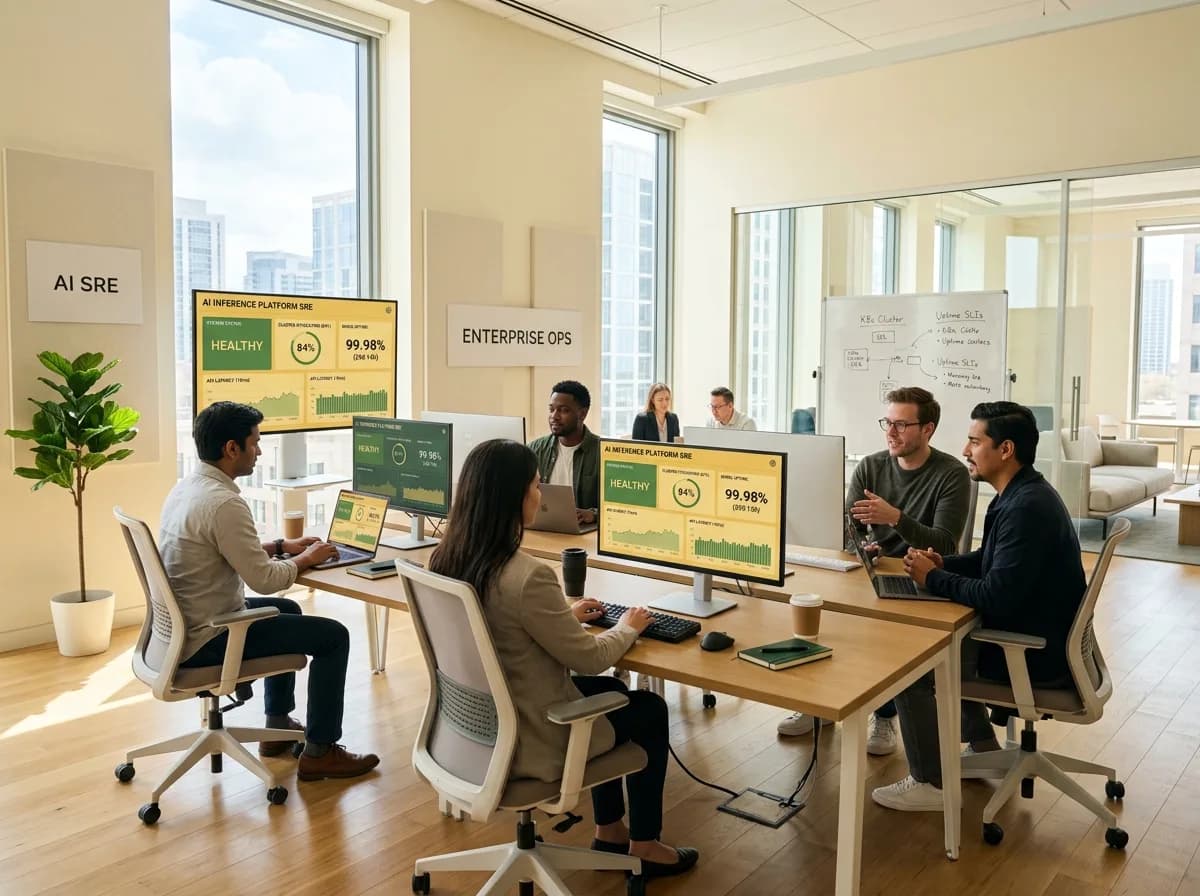
Enterprise AI operations center with real-time telemetry, model lifecycle monitoring, and SLA health dashboards in daylight
24/7 Enterprise AI Operations Center
Active Telemetry & SRE Infrastructure

Autonomous Guardrails, Model Drift Monitoring & Zero-Downtime Governance

Continuous Monitoring
Active
Real-time API latency & P99 error rate tracking
Model accuracy and hallucination rate telemetry
Token burn monitoring and budget alert triggers
Multi-cloud resource utilization & auto-scaling probes
Proactive Optimization
Active
Semantic cache tuning to reduce inference overhead
Prompt template A/B testing from implicit feedback
Multi-tier model routing for low-cost tasks
GPU rightsizing and spot-instance orchestration
Runtime Governance
Active
Secret rotation and PII masking compliance
Immutable audit logs for all AI decisions
Regulatory alignment with EU AI Act & SOC2
Automated canary rollbacks upon drift detection
02 | Core Capabilities Architecture

The Autonomous Operations Fabric:
Everything required to operate AI at scale.

We unite deep MLOps, cloud site reliability engineering (SRE), FinOps cost governance, and active security management under unified operational runbooks.

01 / 08
0102030405060708
Telemetry01Active
Signal:Distributed APM stream verified · 1,420 req/s
Pillar 01 · Telemetry99.9%* Uptime · P99: 18ms

24/7 Production Observability

Real-time synthetic and live monitoring across application frontends, API latency, model token queues, inference accuracy, and cloud cluster resource utilization.

Continuous Telemetry StreamSub-Millisecond Resolution
Operational Runbook Spectrum · Select capability
01
24/7 Production Observability
→
02
Model Drift & Accuracy Management
→
03
FinOps & Inference Cost Governance
→
04
Cloud Infrastructure & SRE Operations
→
05
End-to-End Dependency Tracing
→
06
Continuous Prompt & Workflow Tuning
→
07
Active Security & Runtime Governance
→
08
Multi-Workload Portfolio Management
→
* Availability and latency targets apply to managed gateway routing layers. Token spend reductions reflect observed FinOps benchmarks via prompt caching and tiered SLM routing.
FinOps Token Architecture

Intelligent Model Cascading & Semantic Caching

Stop sending every prompt to expensive frontier models. Our intelligent gateway intercepts recurring queries with sub-10ms semantic vector caches and routes lightweight tasks to compact models.

-40%*
Target Monthly Savings
$4820
Illustrative Simulation
INCOMING:“Customer account status retrieval”
6ms
Tier 0: Semantic Cache (Vector DB)
0ms Token Cost · 99.4% Cosine Similarity Match
Active Route (100% Saved)
Tier 1: High-Speed SLM (8B / Private Endpoint)
Ultra-Low Latency · $0.001 / 1K Tokens
24% Volume
Tier 2: Frontier Reasoning Model (GPT-4o / Claude 3.5)
Full Context Reasoning · Reserved for Deep Edge Tasks
8% Volume
Net Execution Cost: $0.000Cost Avoidance: +$0.040 saved
* Token spend reduction figures represent simulated FinOps outcomes across semantic caching and compact SLM routing. Individual savings vary by workload query repetition.
03 | Production Workload Coverage

Managing every modern AI workload.

From commercial foundation models to custom predictive ML algorithms running on dedicated multi-region clusters, our operational fabric guarantees enterprise SLAs.

6 Production AI Topologies
Workload 01 · Foundation Models99.9%* Availability · P99: 112ms

Prompt Caching & Hallucination Defense

Tracking token usage, answer relevance, latency SLAs, response toxicity, and model version updates across internal and customer apps.
Active Systems TopologyContinuous Observability Link
GPT-4o⇢
Claude 3.5⇢
Llama 3 70B⇢
Semantic Cache
Telemetry:Token Cache: 68% Hit · Hallucination Guard: Active · Latency: 112ms
100% OK
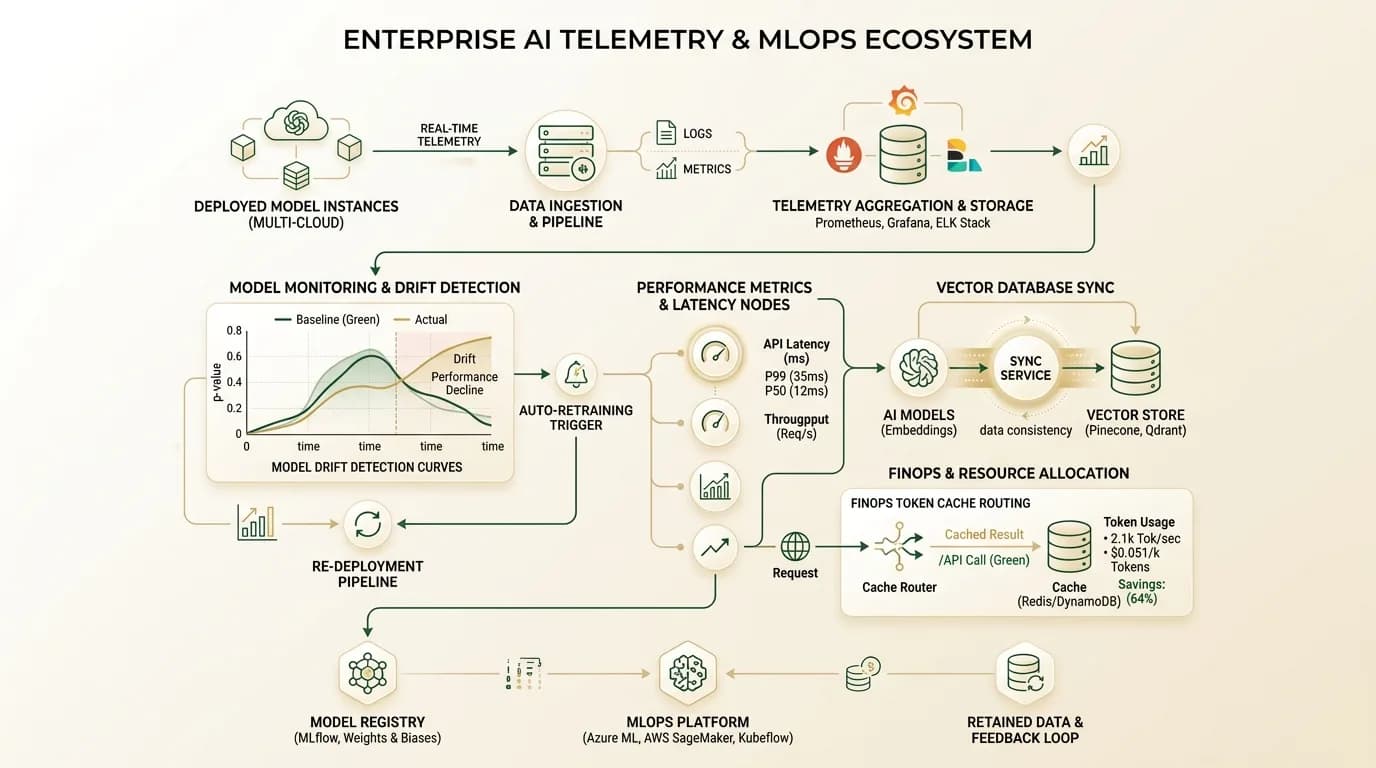
Enterprise AI Telemetry and MLOps ecosystem diagram showing model drift detection, latency nodes, vector DB sync, and FinOps token cache routing
Enterprise AI Systems Topology & MLOps Interconnect
* Target availability for generative model routing layers. Workloads deployed in client private VPCs inherit underlying host cloud infrastructure SLAs.
04 | Operational Transformation

From reactive firefighting to continuous optimization.

Eliminate unbudgeted cloud spikes, silent model decay, and midnight engineer pages with systematic, SLA-backed Day-2 operations.

Concern
✕ Unmanaged Baseline
✓ GlideFlow Managed AI
Incident Discovery
—Users complain hours after the outage begins
✓Automated telemetry alerts within 60 seconds of anomaly
Model Accuracy
—Silent drift degrades predictions unnoticed
✓Continuous drift testing with auto-retraining triggers
Cloud Costs
—Surprise token bills at month-end
✓Daily FinOps dashboards, semantic caching and automated limits
Team Bandwidth
—Core engineers pulled to debug production fires
✓Engineering stays 100% focused on innovation roadmap
Security & Compliance
—Patches and key rotations handled ad-hoc
✓Automated rotation schedules, SOC2 and audit trail logging
05 | Operating Framework Methodology

Disciplined path to operational excellence.

A disciplined 8-stage methodology designed to stabilize, govern, and continuously refine your production environment.

Stage 02 · Real-Time TelemetrySub-Second Telemetry

Monitor: Real-Time Telemetry

Instrument APM distributed tracing, custom model metrics, and FinOps telemetry.

Core Operational Output
✓Full-Stack Observability Suite
Interactive Operational Infinity Engine
Click node to inspect
ENTERPRISEManaged AI● 24/7 SRE LIVECONTINUOUSValue Creation⇄ LEARNING LOOP01Assess02Monitor03Stabilize04Optimize05Maintain06Improve07Scale08GovernUPTIME SLA99.99%FINOPS SAVINGS-40% TOKENSSOC2AUDIT OK98.4%ACCURACY
STAGE 02Monitor24/7 Telemetry
Target: P99: 18ms
Interactive Figure 5.1: GlideFlow Autonomous Lifecycle Infinity EngineClick any of the 8 nodes to inspect active operational deliverables
Live Observability & Self-Healing Loop

Continuous Telemetry & Statistical Drift Defense

01Healthy
API Gateway
18ms1,420 req/s
02Optimal
Inference Engine
94ms48 GPUs active
03Synced
Drift Monitor
Real-timeScore: 0.014
04Fresh
Vector RAG Store
12msSync < 2m ago
Baseline Model Curve Production Stream
Sampling Interval: 1s
P-VALUE: 0.94 · SAFE ZONE
Autonomous Recovery MTTR
< 4.2 Seconds

Automated rollback & dynamic routing kicks in with zero human delay.

Current Prediction Confidence
98.7% Stable

Continuous evaluation against golden test datasets.

* Incident response targets apply to mission-critical severity-1 production events during active coverage. Cost and accuracy figures reflect observed engineering benchmarks.
06 | Production Assurances & Performance

Enterprise SLAs and performance benchmarks.

Rigorous financial and performance commitments governed by real-time contract SLAs.

99.9%*Target Metric
Production Uptime

Target availability backed by automated multi-zone failover and proactive SRE monitoring.

Operational Focus● Active Monitoring
-40%*Target Metric
Inference Cost Reduction

Target cloud and API token savings via semantic caching and model cascading.

Operational Focus● Active Monitoring
< 15m*Target Metric
Incident Response

Rapid severity-1 emergency response supported by automated diagnostics and telemetry.

Operational Focus● Active Monitoring
Zero*Target Metric
Unmonitored Drift

Continuous automated statistical drift testing alerts engineers before predictions decay.

Operational Focus● Active Monitoring
+50%*Target Metric
Internal Team Capacity

Frees in-house data scientists and engineers from 24/7 maintenance on-call duties.

Operational Focus● Active Monitoring
Bi-WeeklyTarget Metric
Optimization Sprints

Continuous tuning of prompts, parameters, and infrastructure throughout the contract.

Operational Focus● Active Monitoring
* Infrastructure & Benchmark Disclosures: 99.9% target availability applies to GlideFlow managed gateway routing layers. Deployments inside client private VPC enclaves inherit host cloud infrastructure (AWS/GCP/Azure) and upstream model provider SLAs. < 15m emergency response applies to mission-critical severity-1 production alerts during active operations coverage. Cost reduction (-40%*), capacity (+50%*), and zero unmonitored drift reflect observed benchmarks across reference enterprise deployments. Built to support SOC 2 Type II and HIPAA requirements inside client cloud enclaves.
07 | Why GlideFlow

Technology shouldn't just run.
It should keep delivering.

We replace passive infrastructure monitoring with active, value-compounding AI engineering and enterprise SRE operations.
* Production availability and capacity figures represent observed operational targets. Formal contractual commitments are customized to client infrastructure tier.
08 | 24/7 Managed MLOps FAQ24/7 Managed MLOps Specifications

Frequently asked managed AI & production operations questions.

Specific metrics regarding 24/7 endpoint surveillance, Kolmogorov-Smirnov drift detection, automated canary retraining pipelines, and 99.9%* target availability.

Our 24/7 managed MLOps coverage tracks endpoint health via Prometheus and OpenTelemetry, monitoring P99 inference latency, token burn velocity, and GPU cluster allocation. We supervise semantic cache hit ratios, tool-calling schema integrity, automated failover routing, and PII masking across enterprise endpoints deployed within client AWS, GCP, or Azure VPC enclaves.

Continuous Operational Value

Ready to safeguard your production AI environment?

Don't let model drift, unexpected token bills, or silent degradation compromise your enterprise AI initiatives. We manage, stabilize, and continuously improve your production systems for the long haul.